Most slow Next.js apps are slow for the same few reasons, and the order you fix them in matters: first stop pages from rendering on every request when they could be cached, then remove data-fetching waterfalls, then cut the JavaScript you ship, then fix images and fonts, then tame third-party scripts, and finally tune caching and revalidation. The first two fix server response time for every page at once; the rest improve what the browser does with it.
Next.js applications can become slower as features, dependencies, data requests, and third-party scripts accumulate. Common causes include rendering strategies that no longer fit the page, sequential data fetching, oversized client bundles, and caching configurations that need review. The causes are rarely exotic. They are defaults nobody revisited, a component that quietly reads a cookie, and a dozen client-side libraries added one at a time. Below is the order we follow for Next.js performance optimization, with how to spot each problem and the impact we expect from fixing it.
Measure before you change anything
-
Field data first. Core Web Vitals from real users (LCP, INP and CLS) tell you which problem visitors actually have. Use Google Search Console’s Core Web Vitals report and Chrome UX Report data where available to understand field performance. You can also collect real-user measurements through Next.js’s useReportWebVitals and an analytics endpoint. These sources have different coverage and reporting limitations, so compare field data with controlled lab tests rather than treating them as interchangeable.
-
Server response time per route. Time to first byte for your main templates, measured from outside your network, cold and warm.
-
Build output.
next buildlists each route and whether it is static or dynamic, plus the JavaScript it loads. -
Lab tools for causes. Lighthouse and the browser’s performance panel show what blocks rendering on a single load.
1. Dynamic-render traps
The symptom: slow time to first byte on pages whose content is the same for everyone, such as product pages, articles or landing pages.
The cause: the page renders on every request when it could be prerendered and cached. In the App Router, reading request-time data such as cookies(), headers() or searchParams ties rendering to the request. In caching models that opt the route into dynamic rendering, request-time data accessed in a shared layout can affect the routes beneath it. The exact behaviour depends on your Next.js version, rendering configuration, and whether Cache Components are enabled. Inspect the current caching guide for your version before changing the rendering strategy. With Cache Components, Next.js asks you to put those reads behind a <Suspense> boundary or cache them, so that the rest of the page can still be prerendered (see the caching guide). Also check: in current Next.js, the docs note that fetch requests are not cached by default, so data you assumed was cached may be fetched on every request.
The fix:
-
Find which component reads request data. Common culprits: a header that reads a cookie to show “Sign in” or “My account”, a currency or locale switcher, A/B testing code.
-
Move that read into a small component behind
<Suspense>, or into the client, so the rest of the page can be static. -
Cache data explicitly with
use cacheor your version’s equivalent, and give it a lifetime. -
Re-run
next buildand confirm the routes now show as static or partially prerendered.
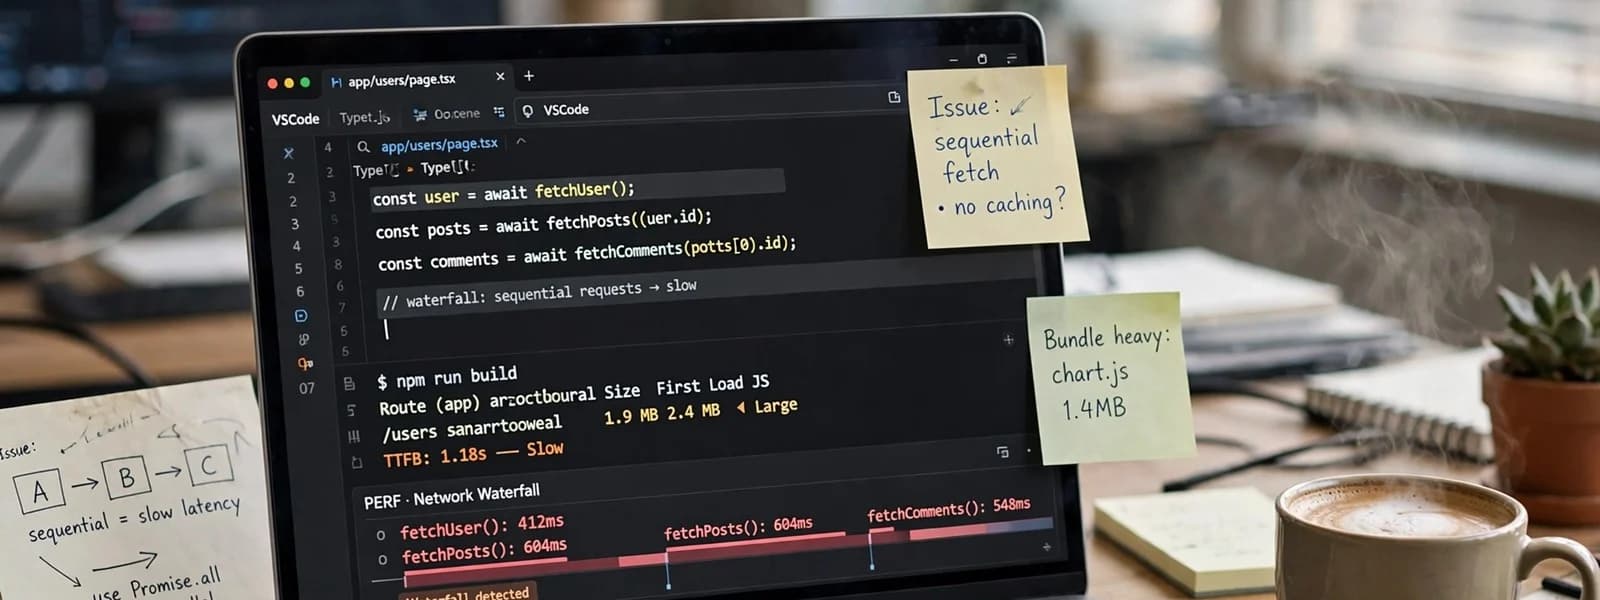
2. Data-fetching waterfalls
The symptom: dynamic pages take as long as all their API calls added together.
The cause: requests that could run at the same time run one after another. The Next.js docs show the pattern: two awaits in a row in one component run sequentially, even when the second does not need the first. Nested components that each fetch on their own can create the same chain across the tree.
[Inline image to add: brand-style diagram of two request waterfalls for the same page, sequential above and parallel below, with no timings on the axis.]
Two request waterfalls for the same page: one with four data requests running one after another, one with the same requests running in parallel and finishing much sooner
The fix:
-
Start independent requests together and await them with
Promise.all, as the data-fetching guide shows. -
Preload data that a child component will need before other blocking work.
-
Stream slow, non-essential sections (reviews, recommendations) behind
<Suspense>so the main content arrives first. -
For a CMS such as WordPress, fetch a page’s content, menus and settings in one GraphQL query where possible. Our headless WordPress guide covers this.
3. Bundle bloat
The symptom: slow interaction (poor INP), long main-thread tasks, and large JavaScript on routes that are mostly content.
The cause: too much code in client components. A "use client" directive high in the tree turns everything below it into client JavaScript. Heavy libraries (date handling, charts, icons, animation, rich-text editors) get imported whole.
The fix:
-
Keep components on the server by default and mark only the interactive leaves as client components (see server and client components).
-
Analyse the bundle (the package bundling guide explains how) and remove or replace the largest packages.
-
Load rarely used UI (modals, editors, maps) with lazy loading.
-
Use
optimizePackageImportsfor libraries with many exports.
4. Images and fonts
The symptom: poor LCP and layout shift, even with a fast server.
The cause: the LCP image is lazy-loaded, too large, or discovered late; fonts swap and shift the layout or block text.
The fix:
-
Use next/image with appropriate dimensions and sizes so the browser receives a suitable image for the viewport. Identify the actual Largest Contentful Paint (LCP) image and ensure it is discoverable early; use the image-preloading option supported by your installed Next.js version when appropriate. Do not preload every image, and do not lazy-load the image that is responsible for initial LCP.
-
Give every image dimensions or an aspect ratio to stop layout shift.
-
Self-host fonts with
next/font, subset them and limit weights. -
Web.dev’s LCP optimisation guide breaks LCP into its parts so you can see which one is slow.
5. Third-party scripts
The symptom: good lab scores, poor field INP; long tasks from scripts you did not write.
The cause: analytics, tag managers, chat widgets, heatmaps and A/B testing loaded early and all at once.
The fix:
-
List every third-party script and its owner. Remove the ones nobody uses.
-
Use next/script and choose a loading strategy according to the script’s purpose. Optional chat widgets and support tools may suit lazyOnload, while scripts needed shortly after the page becomes interactive may require afterInteractive. Test consent requirements and functionality before delaying any analytics, advertising, or essential scripts.
-
Load chat and support widgets on interaction rather than on page load.
-
Keep consent tooling light; it runs on every page.
6. Caching and revalidation
The symptom: pages are cached, but content goes stale, or the cache is so short that most requests miss it.
The fix:
-
Cache content pages with a sensible lifetime and refresh them on demand when content changes, using
revalidateTagorrevalidatePathfrom a CMS or commerce webhook. -
Tag data by what it depends on so one change refreshes only the affected pages.
-
Check how your deployment platform and hosting configuration persist and share the Next.js cache. A new deployment may require cache warming or coordination, depending on the hosting setup and cache implementation. For multiple server instances or ephemeral infrastructure, verify cache persistence and invalidation behaviour rather than assuming every deployment starts with the same cache state.
-
For storefronts, keep product and collection data cached and only cart and account data per-user. The Hydrogen vs Next.js comparison covers how each stack handles this.
The prioritised fix list
Impact is relative and depends on your app; measure before and after each step. We do not quote percentage gains because they vary too much from one app to the next.
OrderFixMain metricExpected impactEffort1Make accidentally dynamic routes static or partially prerenderedTTFB, LCPHigh on every affected routeLow to medium2Parallelise and stream data fetchingTTFB, LCPHigh on dynamic routesLow to medium3Move code to server components, split and trim the bundleINP, TBTMedium to high on interactive routesMedium4Prioritise the LCP image, size images, self-host fontsLCP, CLSMedium to high on image-led templatesLow5Remove, delay or defer third-party scriptsINP, TBTMedium; high if a tag manager is overloadedLow, plus agreement from script owners6Tune cache lifetimes and on-demand revalidationTTFB, freshnessMedium; prevents regressionsMedium
Mistakes when fixing performance
-
Chasing the Lighthouse score. A perfect lab score on a fast laptop says little about real visitors on mid-range phones. Fix what field data shows.
-
Caching personalised content. Making a page static is only safe if nothing on it depends on the visitor. Carts, prices for signed-in customers and account details must stay per-user.
-
Fixing step 4 before steps 1 and 2. Image work on a page that takes seconds to arrive from the server moves the number a little. Server response time comes first.
-
Changing everything at once. Ship one fix, measure, then the next. Otherwise a regression is impossible to trace.
Keep it fast after the fix
-
Add a performance budget per route (JavaScript size, LCP) and check it in CI.
-
Review
next buildoutput on every pull request for routes that flip from static to dynamic. -
Keep real-user Web Vitals on a dashboard and look at it monthly.
-
Review third-party scripts every quarter.
-
The affected routes were tested using a production build, not development mode alone.
-
Server response time and the relevant browser metric were measured before and after the change.
-
Tests include representative mobile and desktop conditions.
-
Any caching change preserves personalised content and correct data freshness.
-
The LCP image, font loading, and layout stability were checked on the actual page.
-
Third-party scripts still perform their required functions and respect consent requirements.
-
Bundle analysis confirms whether client-side JavaScript was reduced where intended.
-
Real-user monitoring is in place to detect regressions after deployment.
Record the route, test conditions, metric, and observed result for each change. Do not claim a performance improvement unless the before-and-after measurements support it.
If the slow app is a headless store, read what headless costs to run too, because slow, uncached rendering also raises hosting usage. If you are about to move a site to Next.js, plan performance into the migration from the start. Our Next.js development team does performance reviews and fixes like these, and our speed optimisation service covers theme-based stores.